
Every test security leader we talk to is working through some version of the same tension: the only realistic way to protect an exam at scale is to automate it, and the one thing you can never fully automate is trust. Reviewers can't watch every session. Investigators can't chase every anomaly. And yet the moment a testing program hands that judgment entirely to a machine, it loses the thing candidates, regulators, and the public actually rely on it for: a human being willing to stand behind the decision.
That tension was the real subject underneath the Conference on Test Security (COTS) 2026, held this November at the University of Cambridge. Two days of security leaders, assessment providers, and technology partners compared notes on a problem that is not getting easier: cheating methods and AI capability are advancing on the same curve, and most organizations are still deciding what "responsible AI in test security" is actually supposed to look like in practice.
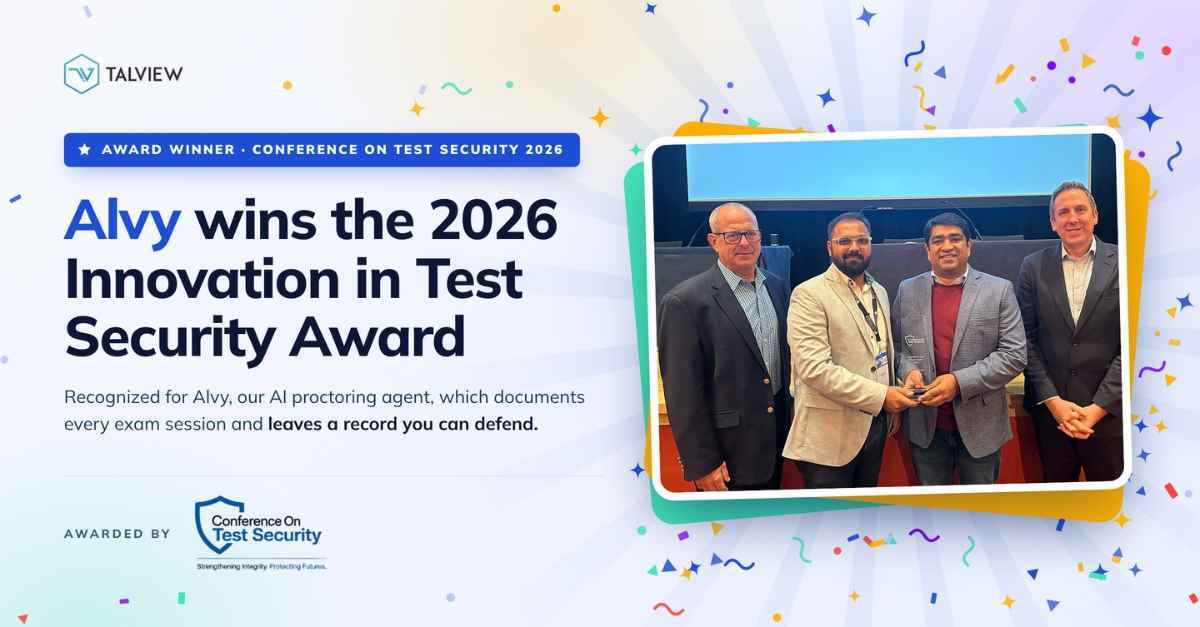
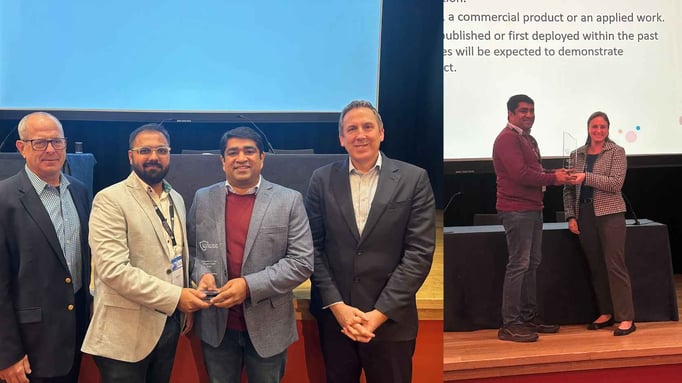
Talview sponsored COTS 2026 because we sit inside that exact question every day. And we left Cambridge with a signal that we're answering it in a direction the industry agrees with: Alvy, Talview's AI proctoring agent, was named the inaugural COTS 2026 Innovation in Test Security Award winner.
How Alvy approaches test security
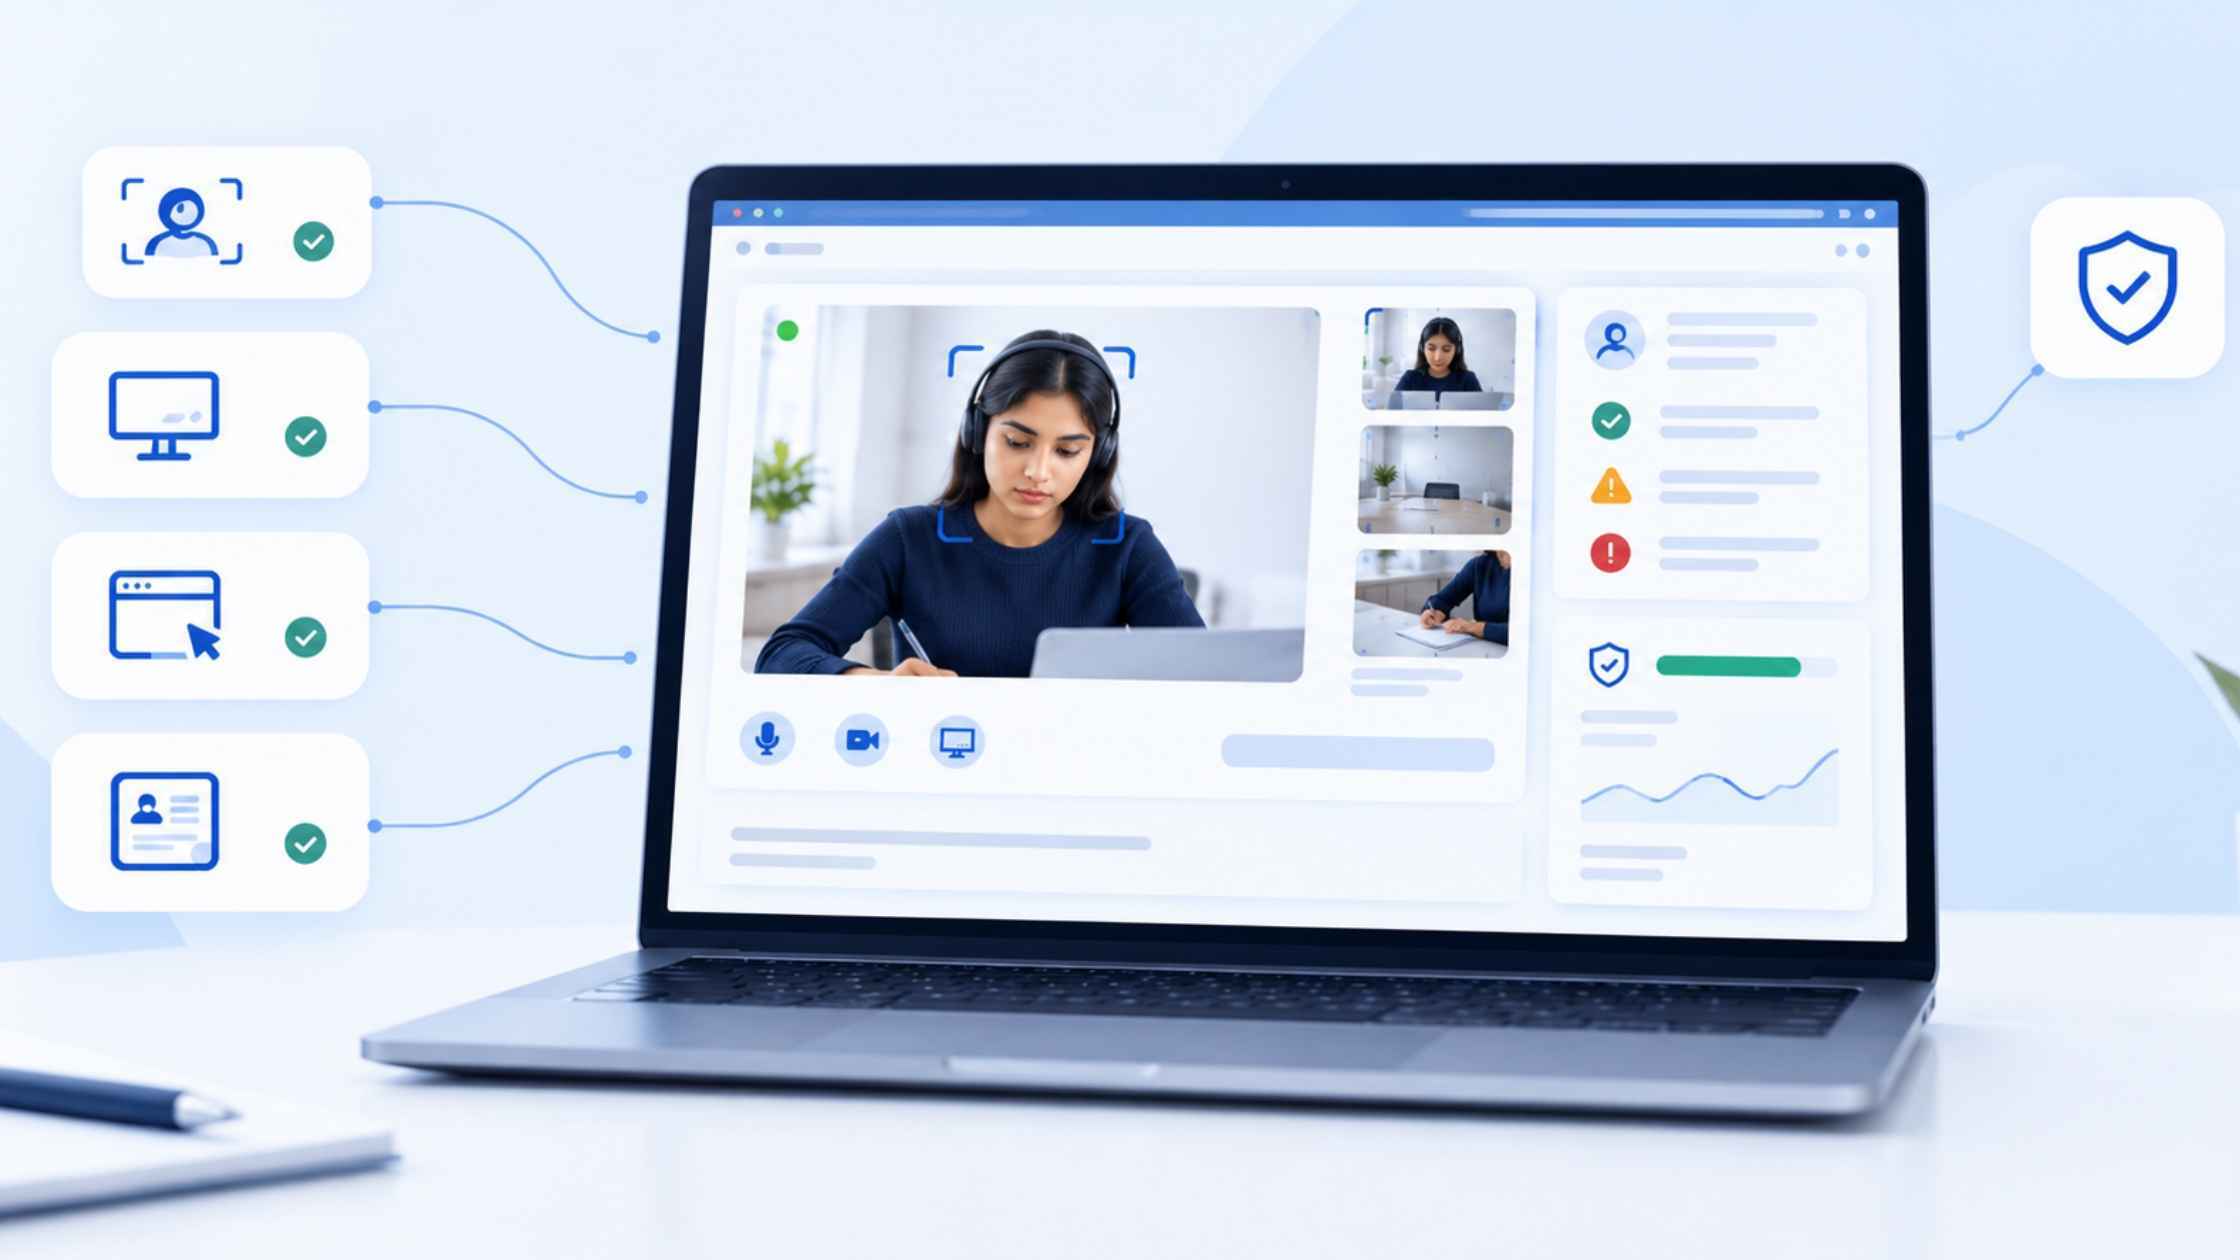
We didn't build Alvy to replace the reviewer. We built it to change what they spend their attention on. Most proctoring tools generate alerts; Alvy generates judgment-ready context, filtering out the noise so reviewers see only the signals that actually indicate risk. The reviewer still makes the call.
That matters because high-stakes testing runs on defensibility. If a result is challenged, a program needs to show exactly what happened and why. Alvy's record, paired with a human decision on top of it, can do that. The COTS judges called out exactly this: not just what Alvy catches, but how accountable it is for what it catches. We see it as one piece of a larger idea: a security partner for high-stakes assessment, where AI absorbs the scale problem while humans keep control of the decisions that need one.
What winning this award means
This is the inaugural year for these awards, and that matters to how we read the result. A panel of test security practitioners, people who deal with fraud and integrity failures firsthand, looked across a newly competitive field and chose Alvy as the clearest example of AI being used the right way. We take that as validation of a stance we've held since we started building Alvy, that the industry doesn't need AI to take over test security, it needs AI it can trust to work alongside the people already doing the job. This award tells us that stance is resonating beyond our own walls, and it raises the bar for what we build next.
Our time at the conference
Talview's CEO, Sanjoe Tom Jose, and Senior Director of Strategic Partnerships, Ayush, attended COTS 2026 to connect with test security leaders from across the industry, not vendor pitches, but practitioners comparing what's actually working. Sanjoe also led a live AIOP demo session for attendees, walking through how Talview is applying AI across test security, integrity, and fairness, rather than just describing it.
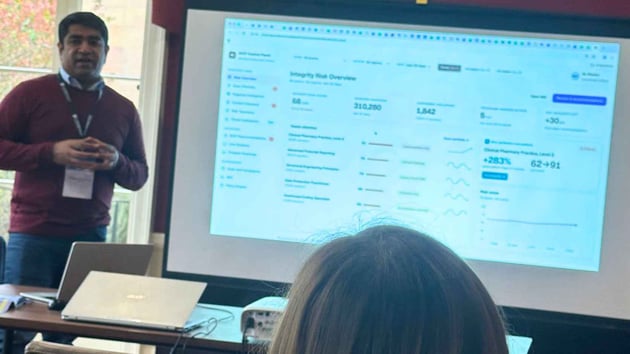
The rest of the conference reinforced why we think the sector is at an inflection point. Sessions covered cross-program collaboration to catch repeat fraud offenders who move between testing providers, AI's expanding footprint across the entire assessment lifecycle, not just the exam room, and a noticeable shift in framing: AI discussed less as a threat to be defended against and more as a member of the security team. Several sessions also pushed in the direction we care most about: human-in-the-loop security stacks, and using a proctor's own confidence level as a new kind of signal. That's the same philosophy Alvy is built on, echoed back from the rest of the industry.
Thank you
An award like this is really a lagging indicator of work that happened much earlier and much less visibly. Thank you to the product and engineering teams who designed and shipped Alvy, and to the customer success and proctoring teams who partnered with Cambridge and others to prove the model out in real, high-stakes conditions. This recognition is theirs as much as the product's.
Thank you as well to the Conference on Test Security for establishing these awards, and to Cambridge English and Cambridge University Press & Assessment for hosting COTS 2026.
We don't think the tension we opened with, scale versus trust, gets fully resolved. We think it gets managed well, or managed poorly, and the industry is still working out which tools help with which. We're glad Alvy is being recognized as one that helps.
Want to see how Alvy approaches this in practice? Explore Alvy.